Choice-complexity formulation
Designed computational representations of the choice set using engine-evaluated candidate alternatives.
UNDER INVESTIGATION // 02
research index ↙COGSCI 2027 · MANUSCRIPT IN PREPARATION
What makes a decision hard when several options are all annoyingly reasonable?
We study whether decision difficulty can be understood not only from the position itself, but from the structure of the available choice set. Using engine-evaluated candidate moves, we build computational measures of choice complexity and relate them to how long people deliberate and the quality of the decision they eventually make.
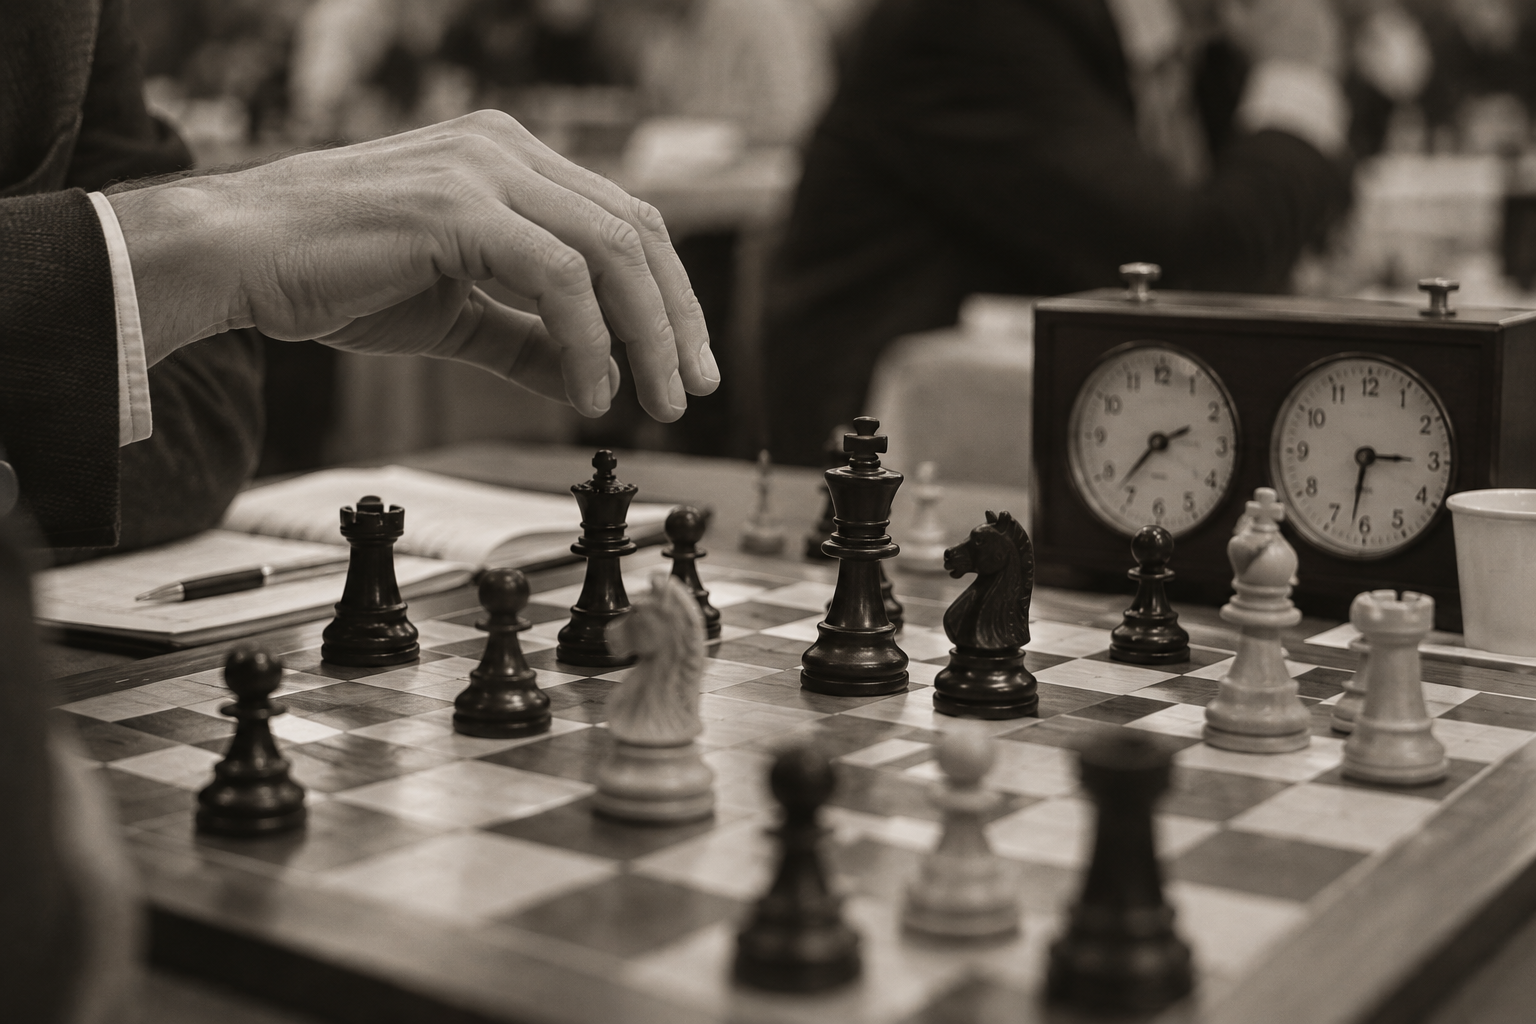
because “there are too many annoyingly reasonable moves here” is not yet a scientific metric
research brief // 02
the model
Difficulty can live in the structure of the choice set.
A position with one clearly dominant move presents a very different decision environment from one where several alternatives remain similarly viable.
We represent this difference using entropy-inspired measures over engine-evaluated candidate moves. A concentrated distribution corresponds to a choice set dominated by one alternative; a more dispersed distribution reflects several competitive options.
Entropy is not intended as a direct measure of subjective difficulty. It gives us a computational description of the decision environment that exists before the human choice is made.
one option dominates
several plausible alternatives
the central claim
Difficulty is not only a property of the person. It can also be a property of the choice set.
from alternatives to outcomes
We begin with the alternatives available in a position and progressively turn them into a representation of the decision environment.
Use engine analysis to evaluate the viable alternatives available in a position.
Transform those candidate evaluations into a relative distribution over alternatives.
Compute entropy-inspired measures describing whether the choice set is concentrated or dispersed.
Relate those measures to decision time and the quality of the eventual move.
engine candidates → choice distribution → entropy → decision time + quality
contribution ledger
Designed computational representations of the choice set using engine-evaluated candidate alternatives.
Built large-scale analysis workflows for extracting candidate evaluations and decision-context features from chess positions.
Connected choice-set measures to human deliberation time and eventual move quality.
Developed the statistical workflow used to compare alternative definitions of complexity and examine within-player variation.
the interaction question
Interactive systems often infer that a person is struggling from what happens after a choice: longer response time, lower confidence, more errors, or poorer outcomes.
But difficulty can also come from the structure of the options the system presents.
This project asks whether we can describe that decision environment computationally and use it to better interpret human deliberation. Chess is useful here because the available alternatives can be evaluated at scale while the human decision itself remains observable.
The broader question extends beyond chess: how should systems represent choice complexity when trying to understand, support, or adapt to human decision-making?
public takeaway
A single difficulty score does not fully describe the decision environment.
Positions with one dominant option and positions with several competitive options can look very different from the perspective of a human decision-maker, even when a conventional engine summary makes them appear similarly difficult.
Our ongoing analyses examine whether measures of broader choice structure help explain variation in deliberation time and decision quality beyond simpler descriptions of the position.
Detailed model comparisons, effect sizes, and final statistical results are staying with the manuscript while the analysis is being finalized.
entropy made it onto the website. the coefficients did not.
methods
large-scale engine analysis · MultiPV candidate evaluation · choice-set modeling · entropy-based complexity · decision-time analysis · move-quality analysis · within-player comparison · statistical modeling
current status
The current version focuses on formalizing choice complexity, comparing alternative representations of the choice landscape, and relating those measures to human deliberation and decision quality.
full research index ↓